Staff Designer, Generative AI Lead · Cross-functional design leadership · ServiceNow · 2024–2026 · Adopted Org-Wide

I made AI behavior
a design decision

Turning model defaults into standards teams could design, build, and measure

At ServiceNow, I helped move AI behavior from something the model happened to do into something the organization could design, measure, and hold teams accountable for.

From

All of the behavioral decisions left to model default.

To

Behavior decisions now belong to product, design, and engineering together.

What I Did

I made AI behavior visible as a set of design decisions

ServiceNow had AI features. It had enterprise data, a context engine, customer workflows, and access to multiple frontier models. But the experience still lost to ChatGPT and Claude because those systems behaved better. They asked when intent was unclear, structured answers more usefully, and handled context, uncertainty, and next steps with more care.

AI behavior is not a model default. It is a product choice.

Who decides how AI behaves

ProblemAI was accurate and still losing.
SignalCompetitors made deliberate behavior decisions ours left to chance.
ShiftI reframed AI behavior as a product decision and wrote it into prompts, PRDs, design reviews, rubrics, and an OKR.
OutcomeA designed case-creation conversation deflected 4× better than the legacy self-service path.
What I owned

I used the tools I had: competitive analysis, research, architecture diagrams, prompt work, evaluation criteria, and a lot of repeated advocacy. I turned that argument into the places the organization already used to make decisions: prompts, PRDs, design reviews, rubrics, design-system guidance, and OKRs.

I owned
  • Reframing AI behavior as a design decision, not a model default.
  • Running competitive analysis across ChatGPT, Claude, Perplexity, Gemini, Agentforce, and Otto.
  • Mapping 13 experience decisions competitors had designed and Otto had mostly left to chance.
  • Building architecture graphics that helped designers understand where behavior was shaped.
  • Defining six behavior levers: intent routing, context usage, source retrieval, prompt guidance, LLM inference, and response structure.
  • Rewriting vague persona guidance into behavior-specific system-prompt instructions.
  • Contributing 11 criteria to the official Conversation Quality Rubric.
  • Advocating for behavior standards in PRDs, design reviews, design-system guidance, and OKRs.
  • Continuing to push until the standards traveled without me in the room.
We partnered on
  • AI-readiness research.
  • Customer interviews.
  • Quality evaluation.
  • Product and engineering implementation.
  • PRD adoption.
  • Design-system publication.
  • Tracking downstream impact.
01 / No Behavioral Quality Bar

The company had AI features. It had no behavioral quality bar.

When the LLM wave hit, ServiceNow rebuilt its AI experiences fast.

Somewhere in the winding response, the answer was there.

Did it contain correct information? If yes, it shipped.

Marked accurate. Still the wrong answer.
Otto
How do I request time off?

At ServiceNow, time-off is administered through several categories, and the process depends on which type of leave you’re requesting as well as your employment classification and tenure. Time-off requests may be submitted through the HR portal under My Benefits, through the Manager Self-Service tab, or by contacting your HR business partner directly. Available categories include vacation (accrued at 1.25 days per month for employees with under 5 years of tenure, 1.67 days per month at 5–10 years, and 2.08 days per month at 10+ years), sick leave, personal days, bereavement leave, jury duty, military leave, and unpaid personal leaves of absence subject to manager and HR approval… (continues for two more paragraphs, through blackout periods, manager approval flows, and a pointer to a separate Leaves of Absence policy)

✓ Marked accurate but Too long Semi-related Assumes context Buries the answer

The problem was not model accuracy. It was behavior quality.

The research behind the gap

The search team pivoted to LLM-generated summaries of knowledge articles, HR policies, and IT requests. The responses were long, wordy, often only semi-related, and assumed a lot about the user. But they were “accurate.”

Accuracy was the only bar, and it was the wrong bar. A response can be factually correct and still fail. Too long to read. Too generic to use. Technically sound while eroding trust through confident guessing.

Research confirmed this was not just an anecdote. Across AI-readiness studies, usability research, customer interviews, and internal quality reviews, the same pattern kept showing up:

Finding 01
Responses were too long and generic

Technically correct, but verbose and poorly prioritized.

Finding 02
Users could not tell what the AI was doing

Transparency was the lowest-scoring dimension in AI-readiness testing.

Finding 03
Data and context were used incorrectly

The system did not consistently use enterprise data, uploaded content, or user history already available to it.

Finding 04
Technical scores did not match perceived quality

Passing the eval and working for the person using it were two different bars.

The research made the gap visible in numbers, not just anecdotes.

In one comparison, QE scores were much higher than user-perceived quality scores across key dimensions:

QE vs. user-perceived quality gap

Accuracy
5596−41
Faithfulness
5897−39
Helpfulness
5297−45
Response fluency
7399−26
Mean
6097−37
User-perceived QE (technical evaluation)

Scores on a 0–100 axis. Third value per row is the gap in points, user-perceived minus QE.

A related comparison showed a 94% mean under QE versus a 74% mean under AI-Readiness testing, with unhappy-task conversations averaging 60%.

Here, the important point is simpler:

The gap made behavior quality impossible to ignore.

02 / The Competitive Gap

I compared Otto against the tools employees actually preferred

I ran a competitive analysis across ChatGPT, Claude, Perplexity, Gemini, Salesforce Agentforce, and Otto. I was not cataloging features. I was mapping behavior decisions: ambiguity, context, source use, response structure, uncertainty, action boundaries, and more.

The pattern was consistent. At every decision point, competitors had made a deliberate choice.

Otto mostly had not.

Designed for Partial Not designed for
Design decisionChatGPTPerplexityClaudeGeminiAgentforceOtto
Asks clarifying questions when unsure
Uses what it knows about the user
Shows where its information came from
Structures responses for scannability
Communicates uncertainty instead of guessing
Signals before taking action n/a

Six of the 13 experience decisions mapped across ChatGPT, Perplexity, Claude, Gemini, and Salesforce Agentforce, the ones where Otto’s gap was starkest.

The contrast was clearest when I ran the same real question through two systems.

User: “I want to switch to a new team.”

Excerpted · responses shortened for space; names and specifics generalized
ServiceNow Otto
Has the data Personalized

Has the data, but not personalized.

“You can switch teams through the internal transfer process, here’s the employee path the knowledge base lays out. You’re encouraged to tell your current manager before officially applying, though it isn’t mandatory, and once you’re in the interview process, transitions are generally completed within two to four weeks after you accept the new role.”

Claude
Has the data Personalized

Does not have the data, but behaves more personally.

“What kind of team switch are you asking about?”

You: “Internal move at my company.”

“Since you’re already established in your current role, reporting to your manager, an internal move usually comes down to a few moving parts. Given your history with your manager, you likely have enough trust capital to have a direct conversation with them, rather than going around them.”

Why the comparison mattered

That comparison bothered me in exactly the right way.

Otto had more raw material than any tool in the matrix: a live context engine, conversation memory, employee history, customer workflows, and enterprise data.

Claude had none of that.

So why did Claude behave as if it understood the person better?

The gap was not data.

It was whether anyone had designed how the system should use what it already knew.

03 / Six Design Levers

I turned orchestration into six design levers

I built a diagram my team still uses: six decision points in the AI pipeline. Five were design decisions. Only one was the model.

01
Intent routing
What the system attempts versus declines.
02
Context usage
What the system believes it should know about users.
03
Source retrieval
What the model trusts and how it builds credibility.
04
Prompt guidance
The behavioral layer governing how the model responds.
05
LLM inference
Generates the response, shaped by decisions 1 to 4.
06
Response structure
How output becomes a clear, formatted experience.
Design decision, 5 of 6 Model, 1 of 6

Most AI failures were not model failures. They were missing design decisions.

How I found the six levers

Across the org, the LLM was often treated as a black box, something engineering tackled and design did not need to understand.

I never accepted that.

ServiceNow does not run its own model. Customers pick one of several frontier models, and the same query across different models got wildly different answers.

If the model alone were the arbiter of quality, shouldn’t those answers have been nearly identical?

And if ServiceNow had direct access to customer data and context those models could only reach through integrations, shouldn’t ours have been better across the board?

That sent me into investigator mode. I read engineering docs, consulted outside research, interviewed people across my team, and pressure-tested the patterns against the AI tools I used every day.

The orchestra analogy

An analogy I use with my team

I used the orchestra analogy because it helped non-technical partners understand the difference between model capability and system behavior.

The model is the raw musical talent. It can play any instrument, any song.

Orchestration is the conductor. It decides when each instrument comes in, how loud it gets, what gets emphasized, and what sequence reaches the audience.

The model
The musicians

Raw talent that can play any instrument, any song, but on its own, everyone starts when they feel like it.

Orchestration · the design layer
The conductor

Decides when each instrument comes in, how loud, in what sequence: the layer where the experience is actually shaped.

The experience
One coherent piece

What actually reaches the audience: the notes, in order, at the right volume, the thing the user hears.

The same musicians can produce a completely different performance under a different conductor.

That is what was happening with AI behavior. The model mattered, but it was not the whole experience. Routing, context, retrieval, prompts, structure, and action boundaries shaped what the user actually got.

Same musicians. Different conductor. Completely different performance.

What each lever changed

The six levers gave design fixed points to attach to.

Intent routing
Should the assistant answer, ask, decline, route, or act?

Context usage
What should the assistant infer from user role, history, permissions, conversation memory, uploaded files, or customer data?

Source retrieval
What source should the assistant trust, and how should it make that source visible?

Prompt guidance
What behavior should the system follow when the request is ambiguous, sensitive, broad, or action-oriented?

LLM inference
What does the model generate after the surrounding decisions shape the input?

Response structure
Should the answer be prose, bullets, a table, a card, a workflow, or a next-step prompt?

This is where the case changed from “AI quality feels bad” to “here are the decisions shaping it.”

If it is a decision, it can be designed.
If it can be designed, it can be measured.
If it cannot be measured, it is not a standard. It is a preference that happens to be shipping right now.
04 / Into the Room

I got design into the rooms where AI behavior was decided

That required different work with different partners.

Engineering

I learned the Context Engine graph layers and harness architecture well enough that my standards were something engineering could build from.

Product Management

I reframed the pitch cycle after cycle, backed by ambiguity research, competitive analysis, and customer evidence.

Leadership

I ran sessions with design leadership who did not yet see how design decisions could shape AI behavior, and I was willing to formally disagree when decisions cut against the evidence.

“Design thinks this matters.”: easy to deprioritize
“Competitors already do this.”: better, still abstract

“Here is what it costs us when we do not have it.”

(the version that finally stuck)

That was the real advocacy work: getting close enough to the decision that design could shape the behavior before it shipped.

Alea builds strong relationships, trust, and credibility with her PM and Engineering partners.Manager · ServiceNow
How I changed the pitch

The reframe was the easy part.

Getting the organization to operate as if it were true took longer.

What I care most about here is not one artifact. It is that I was one of the people inside a large enterprise defining what design’s job is in this new era of AI.

I had a direct hand in framing how our design organization understood AI behavior: not as model output, but as a set of product decisions.

Once I was in the right rooms, the shift was almost anticlimactic.

I did not need to rebuild the whole system to make change. I could point to a decision before it became a product problem. I could say where behavior would default. I could show what it would cost us if nobody owned it.

At first, the argument sounded like this:

“Design thinks this matters.”

That was easy to deprioritize.

Then it became:

“Competitors already do this.”

That helped, but it was still abstract.

The version that finally stuck was:

“Here is what it costs us when we do not have it.”

That changed the conversation. I was no longer asking people to care about an ideal. I was showing them what happened when the standard was missing: lower perceived quality, confused users, missed context, unhelpful answers, and customer paths that could not deflect work they should have resolved.

05 / Where the Model Reads It

I wrote behavior where the model actually reads it

The system prompt was one of the first places design could directly shape the behavior.

The ask arrived in a familiar, misleading shape: give the assistant a persona.

So I did not write a personality sketch. I wrote a specification.

Before: five adjectives, no priority

system_prompt · beforeshipped
1Your name is NowAssist, designed to help users with their tasks and questions.
2Respond in a Firm, Polite, Concise, Sympathetic and Professional manner.
2 lines · 5 adjectives · 0 decisions

After: the same job, written as behavior Written by me

system_prompt · afterexcerpt
## Format
1Lead with the answer, the action, or the point. Never bury it in context, caveats, or setup.
2Default to prose. Use headers, bullets, or tables only when they help the user scan or compare.
3If someone’s task-focused, help them act. If they’re blocked, give the one next step.
4If something’s unclear, ask one question.
## Turn completion
5Close with a clear next move, not a sign-off.
6If the task is done, confirm it and offer the obvious next step.
… remaining sections withheld
2 of the shipped prompt’s sections · every line checkable against a response
Excerpt · snippet shown to hide proprietary company information

The rewrite changed the prompt from adjectives into decisions with observable outcomes.

The rewritten prompt shipped, and an independent platform evaluation scored the product before and after.

Independent · platform evaluation
+4 points

Directness and efficiency: 89% → 93%

Independent · platform evaluation
+14 points

Tone and empathy: 73% → 87%

Before
Otto
What’s the parental leave policy?

At ServiceNow, we value the importance of family time, and we know that welcoming a new child is one of life’s most meaningful moments. That’s why we’re proud to offer a Global Paid Parental Leave program… if you are the birthing parent, you are entitled to 20 weeks of paid leave… if you are in France… (continues to a country-specific clause and an HR handoff)

Warm setup Country-specific clause HR handoff
After
Otto
What’s the parental leave policy?

You get 20 weeks if you’re the birthing parent and 12 weeks if you’re the non-birthing parent under ServiceNow’s global parental leave program, paid at 100% of your regular base pay and running concurrently with any statutory leave you’re entitled to under local law.

If you’re asking about your exact situation in the U.S. vs. another country, I can pull the country-specific guidance next.

Direct, no cushioning Uses what’s known Continues the thread
Recreation · responses shortened; wording illustrative of the patterns before and after the rewrite
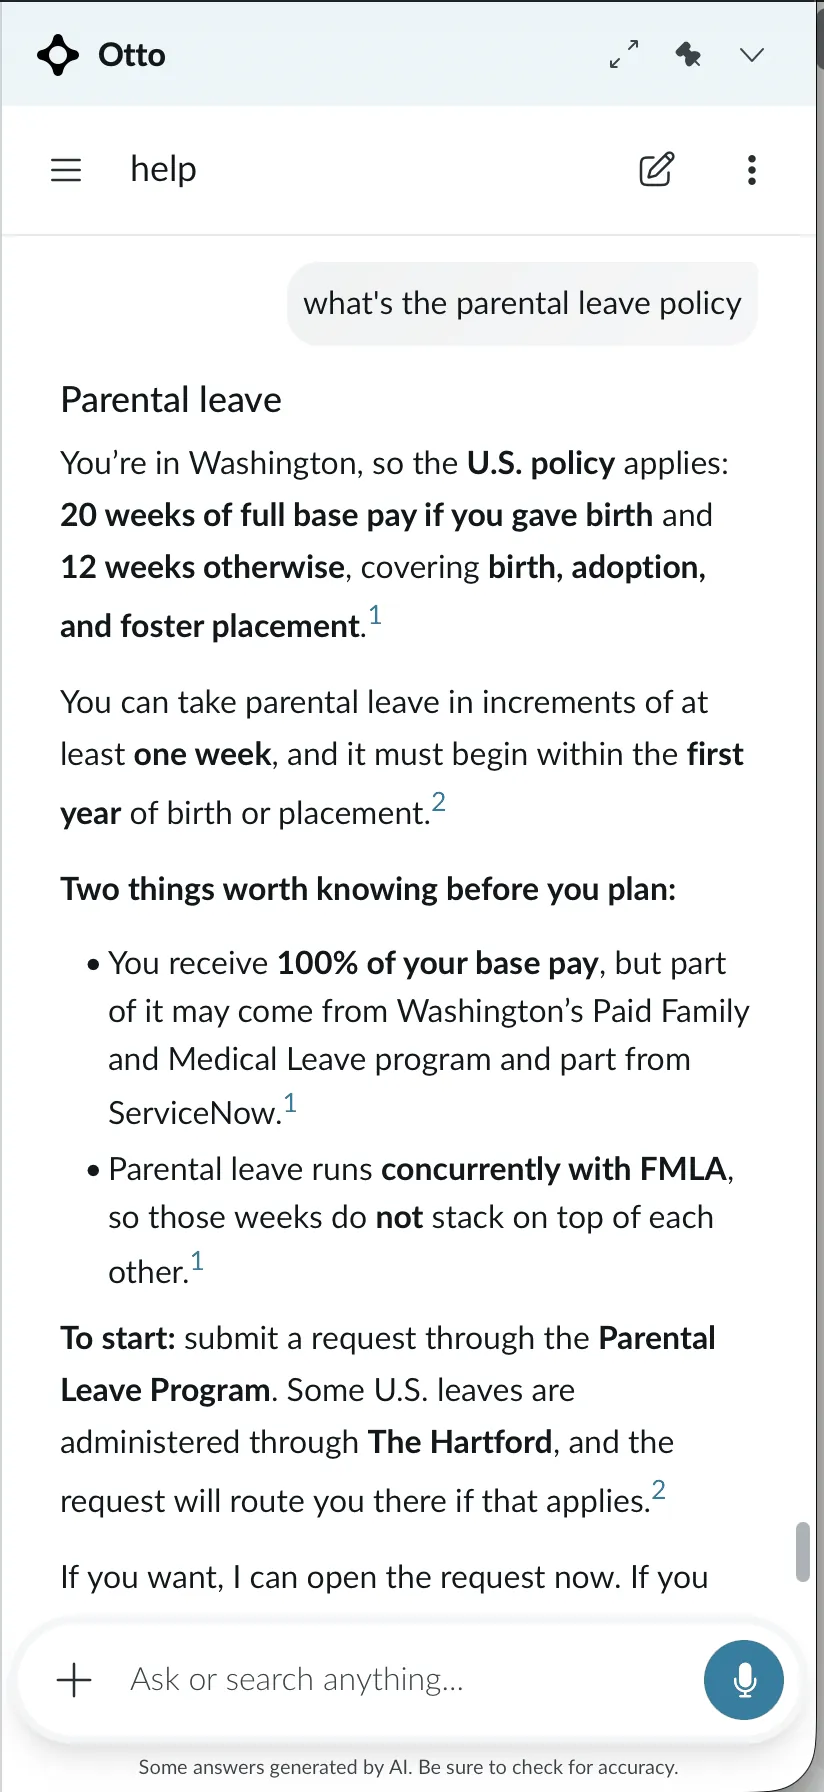
Otto in production answering “what’s the parental leave policy”: it opens with the entitlement (20 weeks of full base pay if you gave birth, 12 weeks otherwise, covering birth, adoption and foster placement), cites its sources with footnote markers, flags that pay is split between Washington’s Paid Family and Medical Leave program and ServiceNow and that leave runs concurrently with FMLA, then offers to open the request.
The shipped answer leads with the entitlement, cites the policy it is reading from, names the two things that change the math, and offers to start the request instead of handing the user to HR.
Actual product · shipped
Leads with the numbers Cites its sources Offers to open the request
Why adjectives were not enough

That framing is how tone work usually gets scoped, and it is why tone work usually changes nothing.

Five adjectives, no order of precedence, and two of them in tension: concise and sympathetic pull against each other on exactly the turns that matter.

Nothing here says what to lead with, what to do when the request is ambiguous, what context to use, when to ask, or how to end.

An engineer building from this has to invent the behavior.

Which means the behavior is whatever the model happens to do.

A persona can describe a vibe.

It does not reliably define behavior.

“Professional” does not tell the assistant whether to lead with the answer or context.

“Concise” does not tell it when to use a table instead of prose.

“Sympathetic” does not tell it whether to comfort the user, solve the task, or do both.

“Polite” does not tell it when to ask a clarifying question.

The rewrite made those decisions explicit enough to evaluate.

That was the point: not better tone, better behavior.

What changed in the answer

The first answer is not unfriendly.

It just does not know who is asking, buries the answer, and hands off to HR for something it should have handled itself.

The second reads cooler. It is also the one that actually helps.

It leads with the answer and names the one real uncertainty instead of guessing.

This was an independent platform evaluation of the product before and after the prompt rewrite.

It supports the claim that specifying behavior in the prompt changed measurable response quality.

It does not prove the full organizational standard by itself.

That is why I treat the prompt rewrite as one important proof point inside a broader advocacy story: it showed that design-written behavior could move product output, which made the larger standard harder to dismiss.

06 / Adoption

The standard traveled without me in the room

The clearest impact signal came from the case-creation journey.

A conversation built to these standards ran beside the legacy self-service path. Same customers, same moment, same intent to open a case.

The only difference was whether the conversation was designed.

4× 11.4% designed conversation deflection vs. 2.75% legacy self-service deflection, case-creation journey, Jan–Jun 2026

I did not build that experience. A teammate did.

The standards became useful enough that other people could build with them, and they traveled without me in the room.

What institutionalization looked like

A framework nobody is obliged to use is a point of view.

To stop having the same argument every quarter, the six decision points had to get into the places where the organization actually commits to things.

That took four mechanisms: the PRD, the quality rubric, a design-org OKR, and design-system standards.

The rubric mattered here because it gave the behavior standards a measurement surface.

Behavioral quality stopped being something designers argued for in reviews and became something the org reports on.

That is the difference between a point of view people can ignore and a standard the organization has to account for.

The standard became real when it showed up in multiple decision systems.

PRD
Product had to name the standard as part of the work, not treat it as a design preference after scope was set.

Design review
Designers had shared language to critique behavior, not just screens.

Rubric
Behavioral quality became measurable enough to sit next to latency and accuracy.

OKR
Adoption had a named owner and review cadence.

Design system
The guidance lived where designers already work, so using it did not require a separate persuasion campaign.

That was the goal: stop making behavior depend on whether I happened to be in the meeting.

How I handled the evidence

Early on, I treated the rubric mostly as a scoring instrument: did the response pass or fail?

What I care about more now is what a score actually licenses you to claim.

A 4× deflection number and an 83-out-of-100 rubric score can both be real, and both be early.

So I distinguish:

  • what is measured from what is directional
  • what I authored from what the platform delivers at scale
  • what the standard influenced from what I directly built
  • what the evaluation proves from what it suggests

That distinction is the thing I now push hardest on when anyone, including me, wants to round a number up.

The numbers behind the impact

These are early, directional figures from a mid-year launch. But they show the kind of impact advocacy is supposed to have: not one better screen, but a standard other teams can use to make better product decisions.

The case-creation journey had three paths:

AI path Legacy self-service Abandoned before choosing

That abandoned group mattered. Nearly a fifth of people left before picking either path. That was a design problem nobody had assigned to anyone.

For the people who did choose a path, the designed AI conversation performed much better.

Deflection by path

Designed AI conversation11.4%
Legacy self-service2.75%
Blended total3.5%

Bars scaled to a 15% axis, not 0–100%, so the difference between paths stays legible.

PathShare of usersDeflection rate
AI path21%11.4%
Legacy path60%2.75%
Abandoned before path19%n/a
Blended100%3.5%

After the original reporting window, the AI path’s deflection rate was later reported at 19%, roughly seven times the legacy path.

That figure is directional: it sits outside the original Jan to Jun reporting window.

The opportunity sizing made the business case clearer.

Opportunity sizing cascade

Case volume100%
Created on the portal87%
Customer-solvable69%
Addressable by deflection28%

Each bar is a share of total case volume, on a 0–100% axis.

That final band represented the cases where better self-service and better AI behavior could realistically matter.

An earlier estimate put that final band at roughly 120,000 cases a year.

AI-Readiness tracking also showed perceived quality moving over the same broader period.

Quality tracking

QuarterPerceived model qualityUser experience
Q1 FY2553%67%
Q2 FY25
Q3 FY25
Q4 FY2577.5%80%

User experience jumped hard, then settled back slightly in Q4 as new capabilities shipped and reset expectations.

Quality is not a finish line. As the product gets more capable, the user’s expectations move too.

07 / What Changed

Design moved from reacting to model output to shaping it

The work changed how AI behavior got discussed, specified, and measured.

BeforeAfter
AI behavior was treated as model output.AI behavior was treated as a product decision.
Accuracy was the main quality bar.Behavior quality could be named, scored, and reviewed.
Design reacted to model output.Design shaped the decisions that produced it.
Prompts described tone with adjectives.Prompts specified observable behavior.
Standards depended on persuasion.Standards lived in PRDs, rubrics, OKRs, and design-system guidance.
I had to keep defending the point.Other teams could build from the standard without me in the room.
Closing

The standards that last describe what AI owes the person using it

We are still early in learning how to write these standards well.

The standards that last will be written at the level of what the system owes the person using it, not which stage of which pipeline happens to enforce it.

I want to help define them, not wait for someone else to turn them into defaults.

Product choices need design language, evidence, and accountability.